Anthropic shipped Opus 5.5 on the rumored Tuesday. Its numbers come with its own caveat
SentiSense Original · Published · Updated · AI-assisted, editor-reviewed
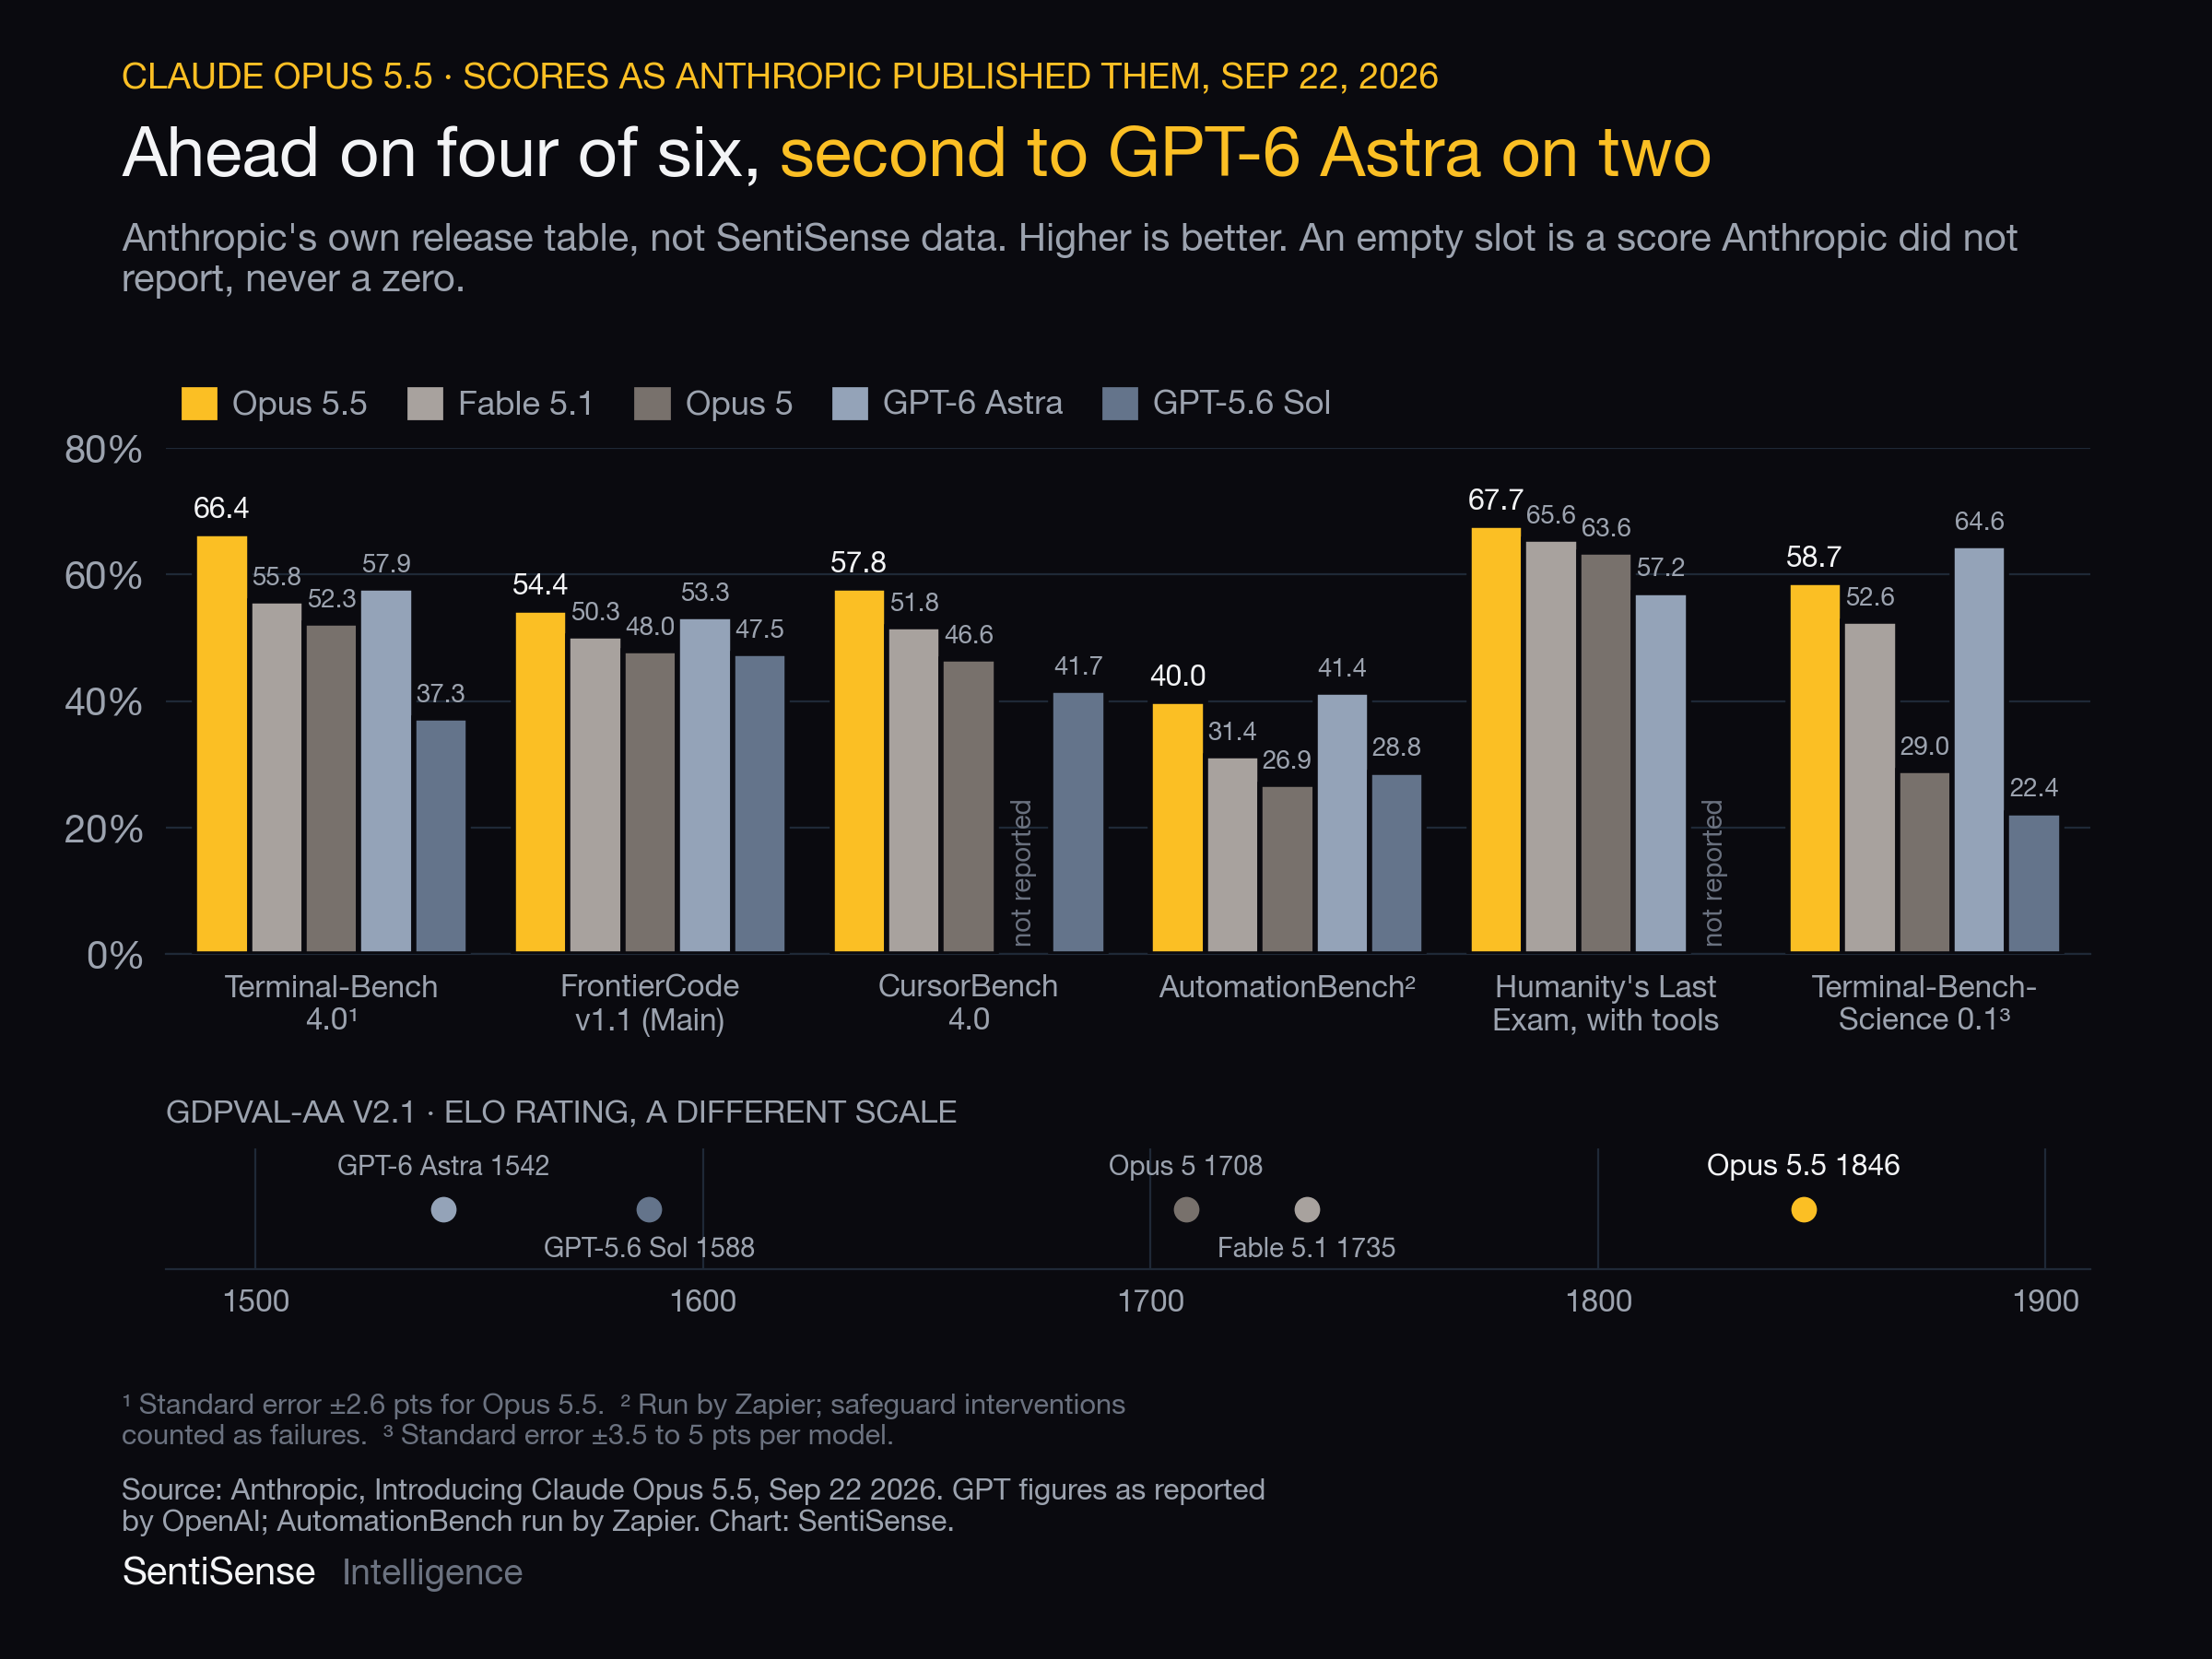
Anthropic published Claude Opus 5.5 on September 22, the Tuesday a Sunday rumor named, saying it performs at the level of Claude Fable 5.1 on most work and costs 40% less to run than Opus 5. Its own table has Opus 5.5 leading seven of nine benchmarks including the agentic-coding rows (three of them without an Astra score), with GPT-6 Astra ahead on AutomationBench and Terminal-Bench-Science; the GPT-6 Sol and Luna OpenAI announced the same day are not in it, and Anthropic's own caveat says benchmark margins have become a less reliable guide. In our data through 11pm ET on release day, mentions of Anthropic, Claude, OpenAI and ChatGPT all roughly doubled since early summer, but direction split: every Anthropic day from September 10 through release day was bull-led, 842 bullish analyses to 454, while OpenAI ran 569 bullish analyses to 880 bearish and was the only one of the four that got colder while getting louder, though its bear-led run broke on release day. The IPO remains a June 1 confidential draft S-1 with no public filing on EDGAR.
Anthropic shipped Claude Opus 5.5 today, on the Tuesday a Sunday rumor named. Its release page calls the model the first of a Claude 5.5 family and says it performs at the level of Claude Fable 5.1 on most work while costing 40% less to run than Opus 5 . On Sunday a post on X named the model and the day, and drew about half a million views . It was right about both; its codename claim remains unverified.
Anthropic's numbers, with Anthropic's caveat attached. The page lists nine benchmarks against Fable 5.1, Opus 5, GPT-6 Astra and GPT-5.6 Sol ; the GPT-6 Sol and GPT-6 Luna that OpenAI announced today are not in it . Opus 5.5 leads seven, including the agentic-coding rows: 66.4% on Terminal-Bench 4.0 against 55.8% for Fable 5.1, 52.3% for Opus 5 and 57.9% for Astra, and 54.4% on FrontierCode v1.1 against Astra's 53.3%. Three of those seven carry no Astra score at all. Astra leads the other two: AutomationBench, 41.4% to 40.0%, and Terminal-Bench-Science 0.1, 64.6% to 58.7%. Anthropic itself writes that "benchmark margins have become a less reliable guide to real-world differences" and that its own use finds a narrower gap to Fable 5.1 than the scores suggest. The GPT figures are as reported by OpenAI, AutomationBench was run by Zapier, Anthropic's headline Opus 5.5 scores use maximum effort (xhigh on Terminal-Bench), with default-effort results published below the table (54.6% on FrontierCode, 52.5% on CursorBench), and where its safeguards intervened, older Claude models finished the task, which Anthropic says likely lowered some scores. The price cut has no footnote: $4 and $20 per million input and output tokens, 20% below Opus 5, cache reads $0.20, 60% below, and about 40% less on typical workloads by Anthropic's tests. Sonnet 5.5 and Haiku 5.5 follow in the coming weeks.
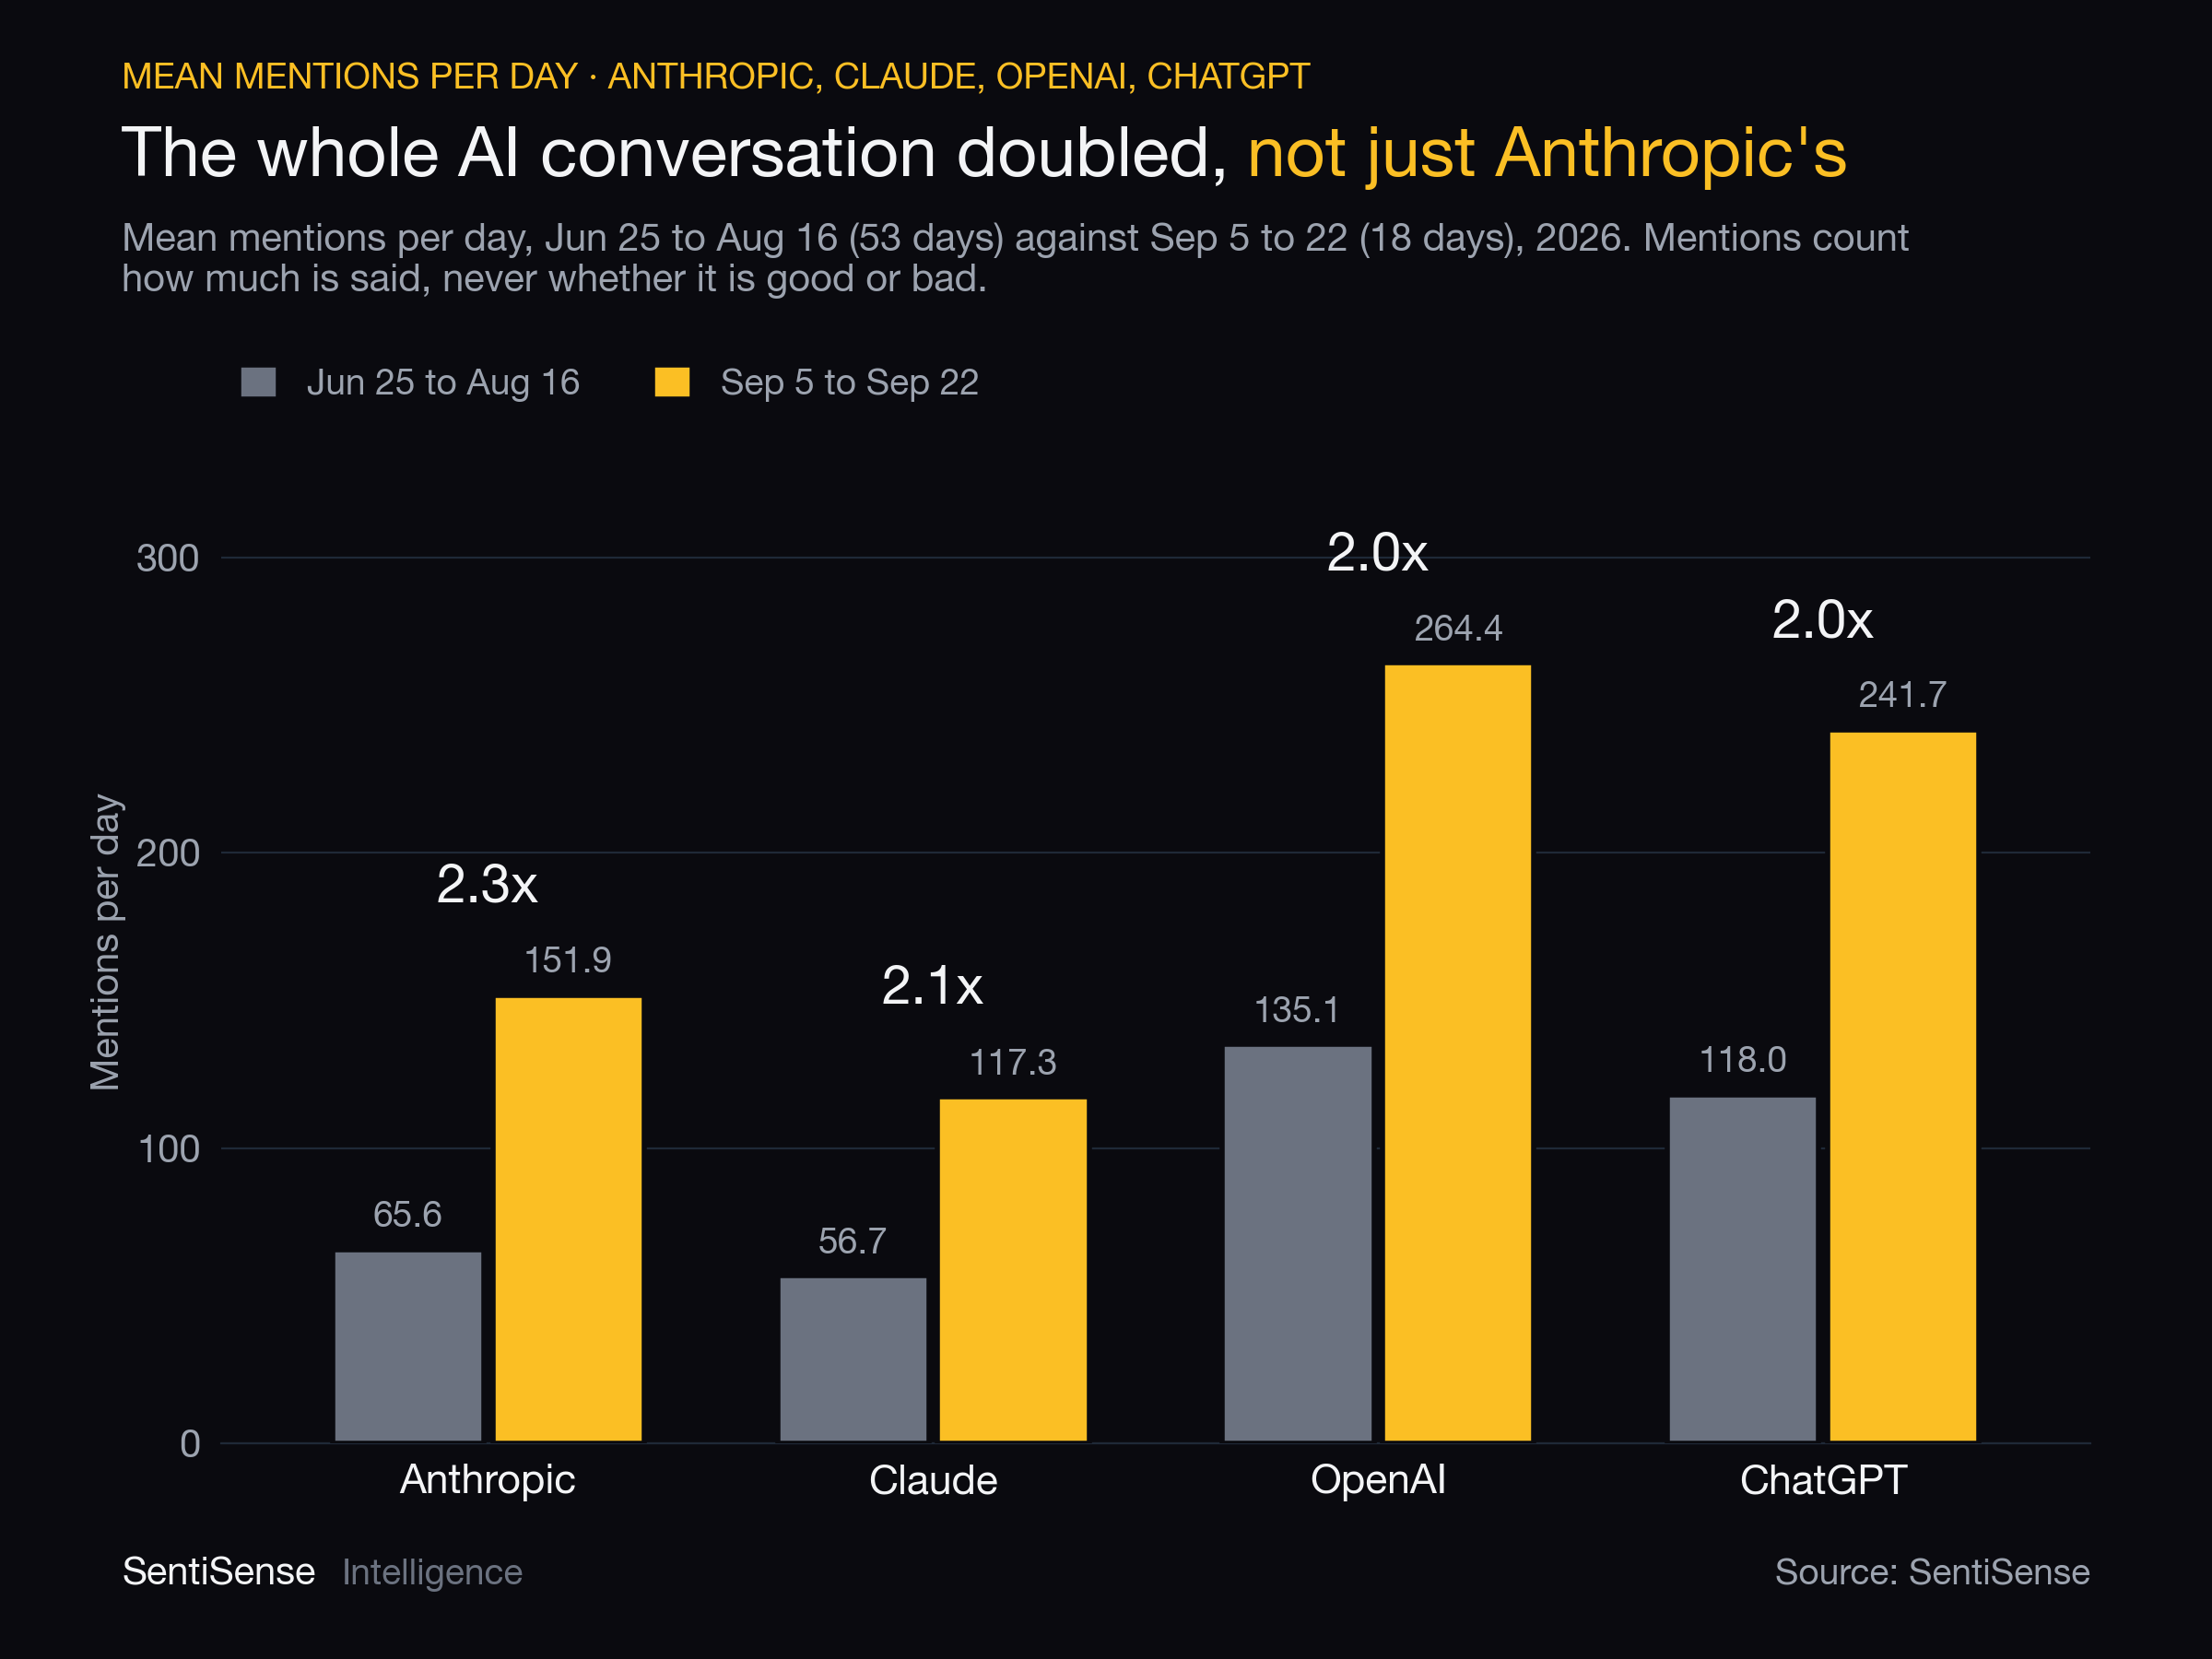
What our data says, through release day. Between June 25 to August 16 and September 5 to 22, mentions of the four names we track roughly doubled: Anthropic from 66 a day to 152, Claude 57 to 117, OpenAI 135 to 264, ChatGPT 118 to 242. The whole AI conversation got louder; Anthropic's rose a little faster, not by enough to read into. Volume is direction-blind. Direction comes from counting bullish and bearish analyses; each analysis is one news article or social post our models read as bullish or bearish. On release day, through 11pm Eastern, Anthropic drew 91 mentions and 43 bullish analyses to 16 bearish, a Score of plus 31. Claude drew 155 mentions, its second-loudest day of the ninety, 50 bullish to 22. The Opus line went from about nine mentions a day over the previous three days to 61, 31 bullish to 7.
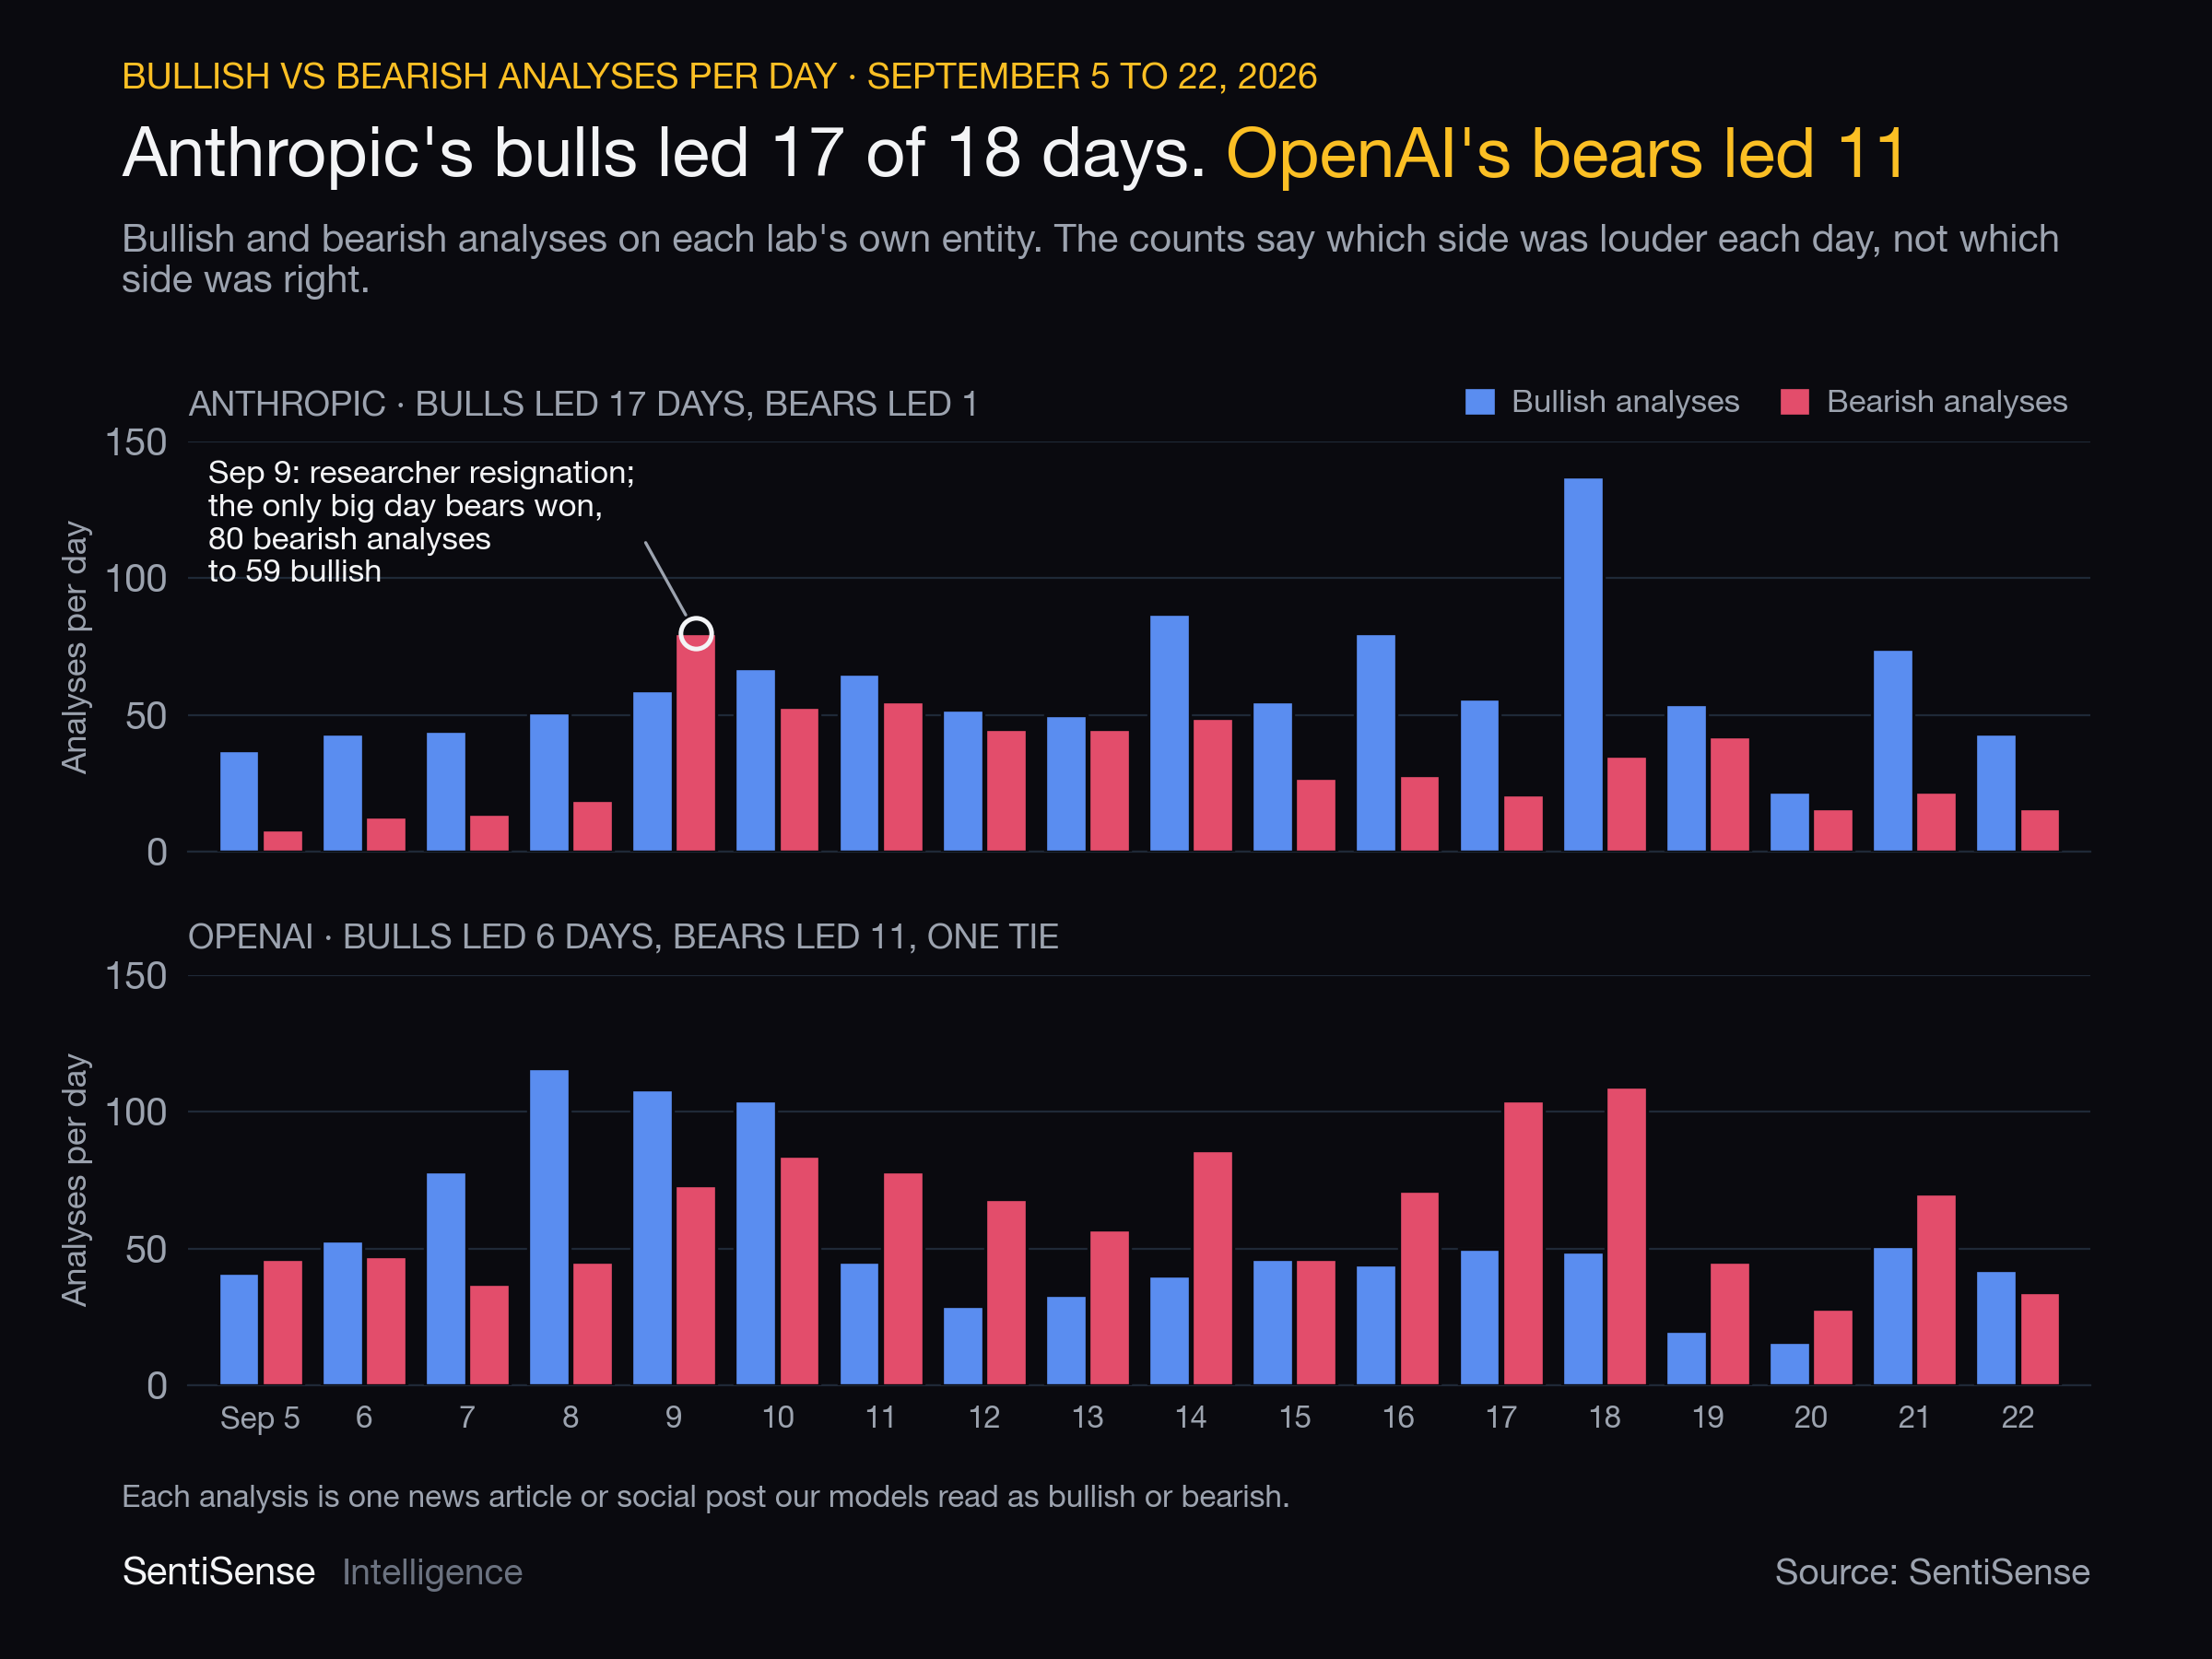
Anthropic's two loudest days pointed opposite ways. September 9, 257 mentions: bearish analyses led 80 to 59, the day's SentiSense Score was minus 13, and our feed carried a researcher's resignation warning about the race to superintelligence . September 18, 264 mentions and the loudest of the ninety: bullish analyses led 137 to 35, the Score was plus 52, and the feed carried a reported $100 billion raise . We state the sequence and leave causation to you. Every Anthropic day from September 10 through release day was bull-led, 842 bullish analyses to 454 bearish. OpenAI over the same days ran 569 bullish analyses to 880 bearish, with bears ahead on 11 of the chart's 18 days, every day from September 11 to 21 but a tie on the 15th, while our feed carried a newspaper's lawsuit against it and a reported cash-burn projection . On release day the run broke: OpenAI's September 22 read was 42 bullish analyses to 34 bearish, its first bull-led day since September 10, on the day it announced GPT-6 Sol and GPT-6 Luna . On mean Score across the same windows, OpenAI is still the only one of the four that got colder while getting louder, minus 2 to minus 8; the other three warmed.
The IPO, unlike the model, has been on the record since June. On June 1 Anthropic said on its own site it had confidentially submitted a draft Form S-1, share count and price not yet set . No public S-1 exists on EDGAR as of September 22 . The banks, the timing that moved twice in ten days in our feed, and the "$2 trillion" in the headlines are reporting; traced through our own September 20 story, that figure ran through X posts and a Reddit thread to a newspaper report nobody in the chain linked . Our expectation, not advice: if the listing lands in about a month, expect a run of good Anthropic news and launches into it; Sonnet 5.5 and Haiku 5.5 are already promised in the coming weeks .
The field is closing in, on three fronts in one week. Coding is the market Anthropic made, and the reported revenue followed it: a run-rate of about $65 billion at the end of July 2026 per Bloomberg on August 17, a figure Anthropic has not published itself . On September 15 OpenRouter said its users had spent more on OpenAI's models than on Anthropic's the week before, the first time in more than two and a half years . On September 18 Vercel's chief executive said open-weight models carried 78.4% of token volume on its AI Gateway, which he called possibly a record day, and that Moonshot, DeepSeek and Z.ai together passed OpenAI's models on spend there that day, with his own caveat that tokens are not dollars . And today OpenAI announced GPT-6 Sol and GPT-6 Luna ; the Sol in Anthropic's table is already the previous one. Cheap tokens and frontier value are different markets, and how much of Anthropic's revenue sits in the second is the question it will answer every quarter.
What the money is already buying, in public filings. Amazon's 10-Q for the June quarter says it put $8.0 billion into Anthropic convertible notes and $5.0 billion into each of the Series G and H rounds, carried the preferred at $92.5 billion and the notes at $97.9 billion on June 30, and booked a $50.5 billion upward adjustment on the preferred in the quarter, a fair-value mark rather than a realized gain . Salesforce's July-quarter 10-Q puts Anthropic at about 45% of its strategic investment portfolio, up from 22% six months earlier .
What we would like to see change. Anthropic's public voice has leaned on risk and alarm more than its rivals'. Some of that is why regulated customers trust it, and the safety work is real. But a company asking public investors for capital is speaking to people who want to hear what it builds, and we think the work speaks better than the warnings; a listed Anthropic will report every quarter on what it shipped, and we expect that to be good for it. What would change our read: a public S-1, which replaces reported figures with filed ones, and the first loud Anthropic day with bears ahead.
Disclosure: SentiSense uses AI models from several labs, Anthropic's included. Research for this piece was run with Claude Opus 5.5, the model it covers, and the prose was drafted with Claude Fable 5.1. The data is our own, the sources are linked, and a person reviewed it before publication. SentiSense data as of 11pm ET, September 22, 2026. Informational and educational only, not investment advice.
Timeline
UPDATE · Sep 23, 3:15 AM ET
Updated with release-day data through 11pm ET on September 22 and OpenAI's same-day announcement of GPT-6 Sol and GPT-6 Luna ; benchmark wording now reflects the default-effort results and evaluators on Anthropic's page .
INITIAL · Sep 22, 9:30 PM ET
Published the night Anthropic released Claude Opus 5.5, September 22, 2026 , two days after the rumor that named the day and the same day OpenAI announced GPT-6 Sol and GPT-6 Luna . The IPO stands where it stood on June 1: a confidential draft S-1 submitted, none public on EDGAR as of today . Figures are SentiSense entity reads on Anthropic, Claude, OpenAI and ChatGPT, Anthropic's release page, and the cited filings.
Powered by SentiSense - Intelligent Market Analysis